The expensive part of running agents is never the part that annoys you
If you run coding agents daily you already have an intuition about where the money goes. It probably points at the retry: that moment when the work fails the check, starts over, and you watch it redo on screen something it had already done.
I had that intuition and wrote a five-point optimisation plan based on it. Then I went to the database for the baseline number I was going to measure the improvement against, and found the retry had fired exactly once in the entire history of the system.
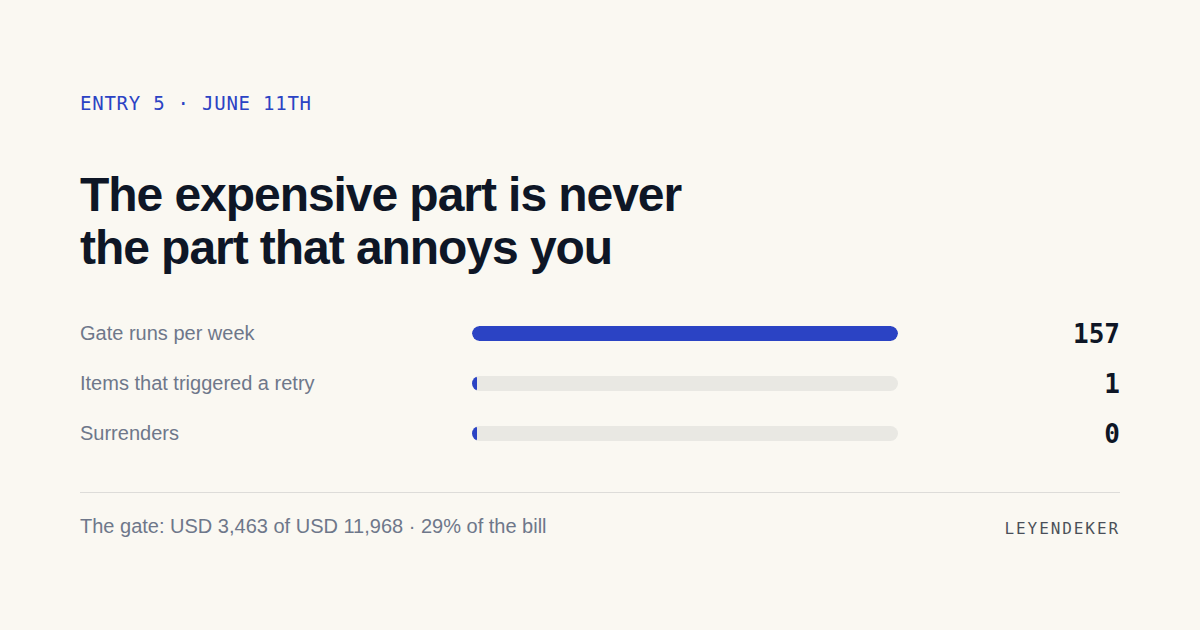
The spend was in a step that had never irritated me, precisely because it worked: the verification that runs before each task closes, which took $3,463 of the $11,968 the system spent in total. 29% of the bill concentrated in the dullest step there is.
The trap generalises to anything you automate with models: what annoys you are the exceptions, because they interrupt; what costs you is the routine, because it multiplies. Without per-step telemetry you optimise what irritates you instead of what bills you.
The obvious suspect
All five points of the plan aimed at the same place: the retry loop.
The reasoning was solid. When work fails the quality gate and has to be retried, you pay for everything again: another agent spun up, another exploration of the code, another implementation, another gate run. It's by far the most expensive operation in the system. And on top of that it was badly implemented: it discarded the previous session, so the second attempt started with no memory of the first.
All of that was true. The five diagnostic points were correctly identified. The plan opened with making retries smarter and continued with minor optimisations.
Then I went to the database to find the baseline number I'd be measuring the improvement against.
What the data said
I found three things that fit nothing I had written:
- A single item, across the system's entire history, had ever produced retry feedback.
- Zero surrenders. The give-up path, carefully designed with its structured incident report, had never once fired.
- The first-attempt pass rate was effectively 100%.
The retry loop I was about to optimise barely ran. I had written an improvement plan for the least-travelled path in the system.
The explanation, once I looked for it, made sense: errors weren't being corrected between orchestrator steps. They were corrected inside each agent's own loop, before the work ever reached the quality gate. The agent iterated on its own output, caught its mistakes and fixed them before handing anything over. To the orchestrator that's invisible: all it sees is a step that finished cleanly.
So my intuition wasn't just wrong about the size of the problem. I was looking at a layer of the system where the problem simply didn't happen.
The number that reordered the plan
The same query surfaced the figure that changed everything. The quality gate — the step that verifies each task before closing it — was running around 157 times a week, averaging 5 to 8 minutes each time.
That was the dominant cost. Not retries, which barely happened: verification, which happened every time.
And the finding held up over time. Today, looking at the cumulative figures, the quality gate has consumed 3,463 dollars out of the 11,968 the system has spent in total. Twenty-nine percent of the bill concentrated in one step.
The plan was rewritten that same afternoon. First, parallelise the gate and cache the test suite. Retry work was demoted to a cheap robustness improvement, for when the worst case actually occurs.
Why intuition pointed the wrong way
I've thought a fair bit about why I got it so clearly wrong, because the error wasn't analytical: it was perceptual.
Retries hurt. You see them on screen, they show up as a loop repeating, they feel like waste while they happen. They're visible, noisy and frustrating.
The quality gate didn't hurt because it was routine. It ran every time, it was part of normal operation, and for exactly that reason it was invisible. Nobody looks twice at a step doing what it's supposed to do.
Which is why perception runs backwards from spend: the exception takes all your attention while it happens and never shows up on the invoice; the routine takes none and is the whole invoice.
A note on how I recorded the mistake
When I rewrote the plan, I didn't delete the original diagnosis. I added a dated note above it with the recalibration: what I had believed, what the data showed, and how that changed the priority.
I could have rewritten the document cleanly, with the correct diagnosis from the start. I didn't, for a practical reason: the wrong diagnosis still has value. It explains why the system is built the way it is, and it reminds me that the reasoning behind it was sound — reading the code, anyone would have reached the same conclusion.
A plan that hides its own diagnostic errors becomes an internal marketing document. One that leaves them visible, with the date attached, is a record of how something was learned.
Where to start in your own system
The order isn't guessed, it's queried. Before writing an optimisation plan, list your pipeline's steps with two columns — what each run costs and how many times it runs per week — and sort by the product of the two. Frequency is what surprises you, almost never unit cost: the wildly expensive step that runs once a month isn't your problem.
The first task in the reordered plan sounded trivial: stop running the full suite when the code hadn't changed. It had a trap that nearly had me certify as passing a codebase that was never tested, and that's what the next entry is about.